How to Sync Stripe Data to Postgres: Webhooks, Data Pipeline, or Both?
Stripe can now stream your payments, customers, and subscriptions straight into Postgres. Here is when that replaces your webhook code, when it does not, and how to set it up safely.
 Tayyeb FeroziSenior Full Stack Developer
If you run a SaaS product on Stripe, at some point you need to sync Stripe data to Postgres: to show a billing page, gate features by plan, or answer "how much did we make from annual plans last quarter?" without exporting CSVs. Until now that meant writing and babysitting webhook handlers. On October 15, 2026, Stripe added a managed option. This guide compares the three realistic approaches, shows when each one fits, and walks through a safe setup, with a real query at the end.
What Stripe announced
Stripe Data Pipeline, which already exported Stripe data to warehouses, now offers real-time sync to Postgres. According to Stripe's announcement, you connect your database, select the Stripe tables you need, and Stripe backfills them and then keeps them updated as your data changes. No code is required, and Stripe says it works with Postgres hosted on Supabase, AWS, Neon, Databricks Lakebase, and other providers.
A few details matter before you plan around it:
- It is in public preview. Expect rough edges and possible changes.
- Updates usually land in seconds. The real-time sync documentation says changes typically appear within a few seconds, but during the preview a row can briefly show an earlier state.
- Some updates are slower. During the preview, updates to tables such as
payment_intents,setup_intents,invoice_items, andquotes, and new rows incheckout_sessions, can take up to 10 minutes. - It covers listable API resources. Charges, customers, subscriptions, invoices, prices, and products are all available. Single objects, such as your account balance, are not.
- It is one-way. Stripe stays the source of truth. You still change things through the Stripe API.
The three ways to get Stripe data into your database
1. Webhooks you build yourself
This is what most SaaS apps do today. Stripe calls an endpoint on your server for each event, such as customer.subscription.updated, and your code writes the relevant fields into your own tables.
It works, but you own every failure mode. Stripe can deliver the same event more than once and does not guarantee order, so handlers must be idempotent and must not let an older event overwrite newer state. If your endpoint is down, you rely on retries. If your handler has a bug, your data quietly drifts from Stripe, and you only find out when a customer who cancelled still has access. Most mature teams end up adding a nightly reconciliation job on top.
2. Stripe Data Pipeline real-time sync
Stripe does the copying. You get a schema in your own database with one table per Stripe object, columns that mirror the API, a _raw_data column holding the full JSON object, and an _updated_at timestamp. Stripe also says it audits the synced records against Stripe on a regular basis and fixes discrepancies, which replaces the reconciliation job you would otherwise write.
What it does not do is tell your app that something just happened. A synced table is a place to read from, not a trigger.
3. Open-source and third-party sync tools
Before Stripe shipped this, the gap was filled by tools like Supabase's open-source Stripe sync engine and ETL services such as Estuary, CloudQuery, and Weld. They are still sensible if you need a destination Stripe does not support yet, want to self-host every moving part, or already pay for an ETL tool that handles your other data sources.
Which approach should you use?
For a typical B2B SaaS product, our recommendation is both, with clear roles:
- Use webhooks for actions. Provisioning a workspace after checkout, revoking access when a subscription ends, sending a "your card failed" email. These need to happen the moment the event fires, and a handful of focused handlers is easy to keep correct.
- Use the synced tables for reads. Billing pages, plan checks in the admin panel, revenue dashboards, support tooling, and anything that joins Stripe data with your own. This is where hand-written webhook code tends to sprawl, and where the managed sync removes the most work.
Some rules of thumb:
- Early MVP with one plan: a few webhooks and a
plancolumn on your accounts table is still fine. Do not add infrastructure you do not need yet. - Growing product with several plans, trials, coupons, or usage billing: turn on the sync and stop mirroring subscription fields by hand.
- Finance or ops asking for numbers every week: the sync pays for itself the first time someone answers a revenue question with SQL instead of a spreadsheet export.
One caution while the feature is in preview: do not make the synced tables the only thing standing between a user and paid features. Keep the webhook that grants and revokes access, and treat the sync as the read model.
How to set it up safely
The Postgres configuration guide is short, and most of it is good database hygiene. The steps we follow:
- 1.Check your version and storage. Stripe requires PostgreSQL 13 or later. If you sync every table, Stripe suggests planning for roughly 1 GB of storage per 100,000 charges you have processed, and turning on storage autoscaling if your host offers it.
- 2.Create a dedicated user. Never hand Stripe your admin credentials. Stripe's docs give the exact statements: create a
stripeuser and grant it onlyCONNECTandCREATEon the database. Supabase and Neon users can skip this and connect through OAuth. - 3.Give it its own schema. Stripe creates and owns the schema, named
stripeby default. Use one schema per Stripe account, and nothing else in it. - 4.Lock down the network. Allow inbound connections only from the IP ranges Stripe lists, and require SSL. Use the advanced setup if you want hostname and certificate verification.
- 5.Start with the tables you need. For most SaaS apps that is
customers,subscriptions,invoices,prices, andproducts. You can enable more later. - 6.Treat the tables as read-only. Stripe warns that writing to its tables can cause sync errors and inconsistent data. Put your own columns in your own tables and join.
What you can do with the data
The payoff is that Stripe data becomes just another set of tables. Here is a query we would use for a support view: every user with a live subscription, their status, and when it started, joined to the app's own users table.
select
  u.email,
  s.id as subscription_id,
  s.status,
  to_timestamp(s.created) as started_at,
  s.cancel_at_period_end
from public.users u
join stripe.subscriptions s on s.customer = u.stripe_customer_id
where s.livemode
  and s.status in ('active', 'trialing', 'past_due')
order by s.created desc;
Two details to notice. Stripe timestamps such as created arrive as Unix seconds in a bigint column, so convert them with to_timestamp. And nested objects, such as subscription items or metadata, are stored as jsonb, so you query them with Postgres JSON operators instead of extra tables. This is the kind of work that used to need a week of webhook plumbing and a migration for every new field.
Where we have seen this matter
Billing state is where most SaaS bugs hide. On the America Working subscription platform, we built Stripe end to end: checkout, plans, webhooks, and dunning, with custom server-side delivery rules for each subscription tier, on Next.js and PostgreSQL. Access is checked at the database layer, so a bug in a route handler cannot leak paid data to free users.
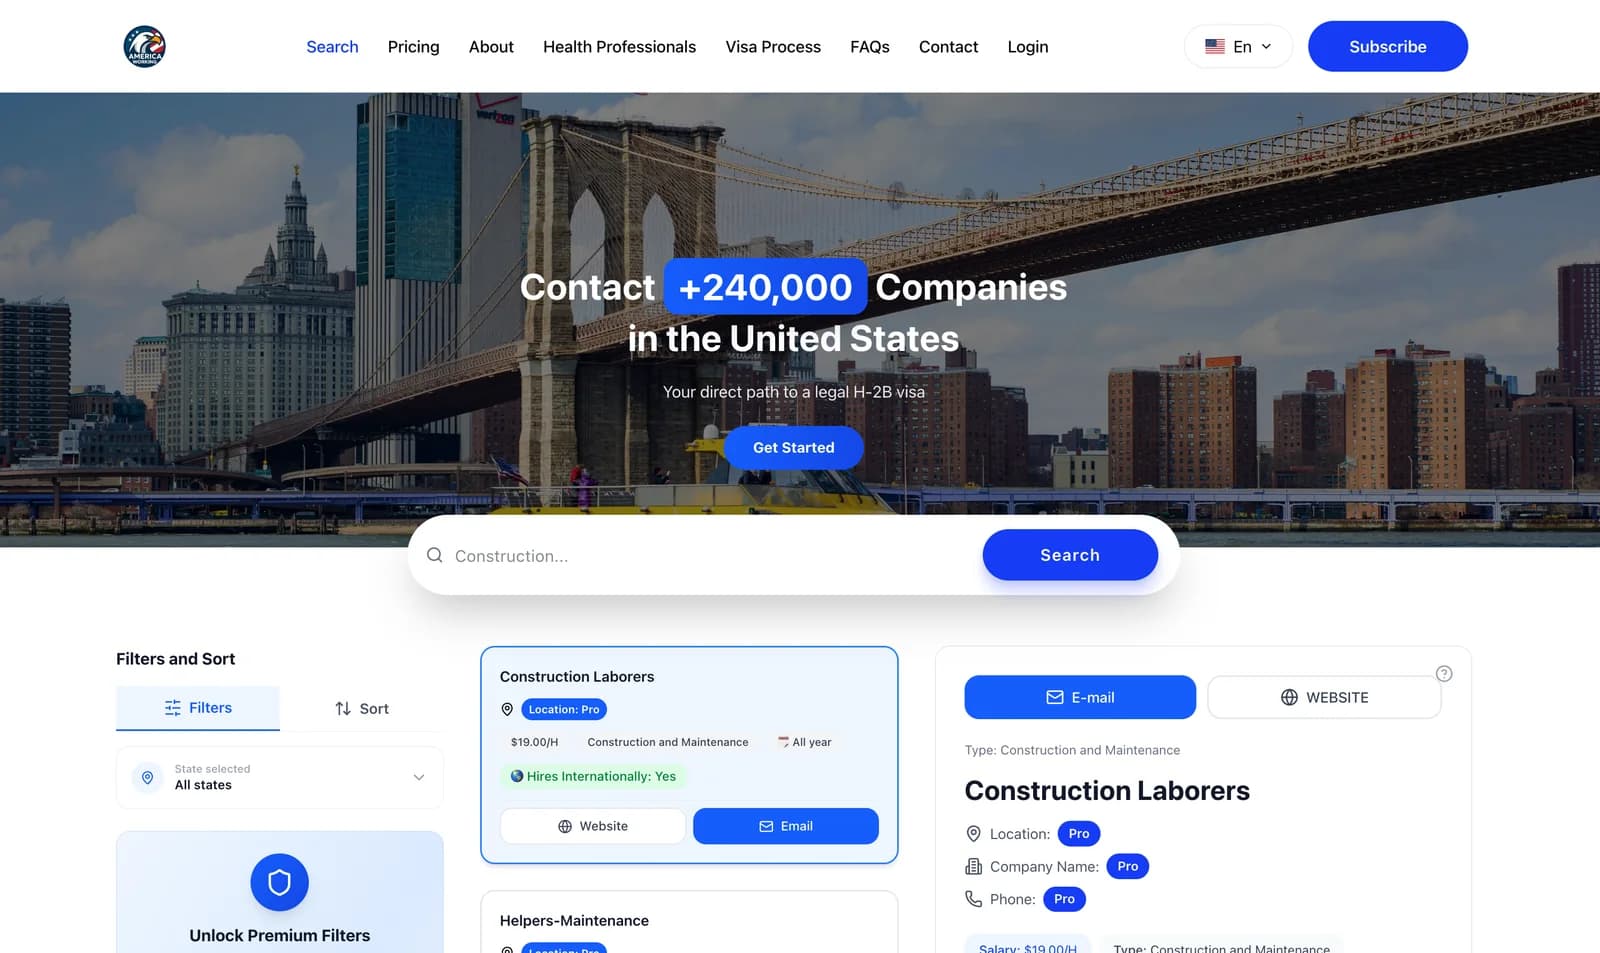
That split is exactly the pattern this guide recommends: webhooks drive what happens, and the database is where truth is read and enforced. A managed sync now removes the most tedious half of that work. If you are choosing the rest of your stack, our guide to the stack we use for SaaS explains why we default to Postgres in the first place, and how to scale a SaaS application covers what to do as that database grows.
The bottom line
To sync Stripe data to Postgres in 2026, you no longer have to write the plumbing yourself. Turn on Stripe Data Pipeline for the tables you read, keep a small set of idempotent webhooks for the actions that must happen right away, and give Stripe a locked-down user and schema of its own. While the feature is in preview, keep access control on your webhooks and treat the sync as your read model.
If you are building or untangling billing in a SaaS product, this is everyday work for our SaaS development team. Tell us about your product and we will send a fixed-scope plan.
Frequently asked questions
- Can Stripe sync data directly to Postgres?
- Yes. Stripe Data Pipeline now offers real-time sync to a Postgres database you own, in public preview. You connect the database in the Stripe Dashboard, choose the tables, and Stripe backfills them and keeps them updated.
- Do I still need webhooks if I use Stripe Data Pipeline?
- For most SaaS apps, yes. The synced tables are ideal for reading and reporting, but webhooks are still the cleanest way to trigger an action at the moment something happens, such as provisioning access after checkout or emailing a customer when a card fails.
- Which Postgres hosts work with Stripe real-time sync?
- Stripe says any PostgreSQL provider works as long as it meets the requirements, including Supabase, Neon, AWS, DigitalOcean, and Databricks Lakebase. Supabase and Neon can connect through OAuth, while other hosts use a connection string or the advanced setup.
- Can I write to the Stripe tables in my database?
- No. Stripe's documentation says you can run read-only queries and connect analytics tools, but external writes can cause sync errors and data inconsistencies. Keep your own data in your own schema and join to the Stripe tables.
- Is the sync two-way?
- No. Data flows from Stripe into Postgres. To change a subscription, a price, or a customer, you still call the Stripe API, and the change then flows back into your database through the sync.
Written by
Tayyeb Ferozi
Senior full stack developer at Code Nativex, delivering full-cycle products from the database and backend to the user interface.
Meet the team